Security Now 1103 transcript
Please be advised that this transcript is AI-generated and may not be word-for-word. Time codes refer to the approximate times in the ad-free version of the show.
Mikah Sargent [00:00:00]:
Coming up on Security Now, Steve Gibson is here. Who are you if you hand over the keys to 98% of your code and you're handing it over to a 27-year-old? Turns out you're Cisco. Yeah, that plus loads more coming up, including a huge financial heist in the crypto market, an AI kill switch and what that would actually look like, and well, some really worrying reverse engineering in terms of consumer crypto. All All of that coming up on Security Now. Podcasts
TWiT.tv [00:00:33]:
you love. From people you trust.
Mikah Sargent [00:00:38]:
This is TWiT. This is Security Now, episode 1103, recorded Tuesday, November 3rd, 2026. Exposing bad consumer crypto. Hello and welcome to Security Now, the show where every week we talk about what's going on in the world of security, well, cybersecurity anyway, with our one and only Steve Gibson. Hello, Steve.
Steve Gibson [00:01:09]:
Micah, great to be with you for our 3rd and final week while Leo is off somewhere globetrotting.
Mikah Sargent [00:01:18]:
Yeah, exactly. Off somewhere doing something. It has been a pleasure to be here with you. And I think last week's episode was very, very well received and wanted. And so that was great to see some of the feedback about everything going on with PHP and your conversation afterward about that strategic plug pull, as it were. So great work.
Steve Gibson [00:01:42]:
Well, I think we have something also really interesting. It is, as is cybersecurity now, it's AI adjacent, but not actually, it's enabled one of these other things that's enabled by the— they're actually, in this case, the reverse engineering capabilities which are being leveraged. And, uh, some really interesting findings by, uh, some guy who calls himself the Binary Ninja. So, uh, uh, so today's podcast, 1103, Uh, for— oh look, it's 11:03.
Mikah Sargent [00:02:25]:
What are the odds there? Someone calculate them. I'm feeling a little excited.
Steve Gibson [00:02:31]:
That's, uh, Exposing Bad Consumer Crypto. And, uh, the, the takeaway will— well, I'm not gonna step on the takeaway, so we'll wait for that. Yeah, so, um, the— we're gonna talk about Uh, this bizarre, like, thing that happened with Cisco. A bunch of our listeners sent me, uh, notes to make sure that this was on my radar, where Cisco has given a lone 27-year-old the task of recoding all of Cisco's software. For some reason, the figure 98% is quoted. I don't know what the other 2% is. Maybe that's the the corporate management software, who knows what. But anyway, uh, this kid gets the ear of the CEO and says, hey, I can fix all this.
Steve Gibson [00:03:26]:
And the guy goes, okay. Anyway, we'll talk about that.
Mikah Sargent [00:03:29]:
Must be his nephew or something.
Steve Gibson [00:03:31]:
It's bizarre. And, and the politics of this— well, anyway, there's a lot to be said. Uh, we've also got a serious but not earth-shaking vulnerability But again, serious, found in PXE booting. The largest by far, meaning $6.3 billion with a B, financial heist in history that, of course, involved crypto because you can't move $6.3 billion without it being, you know, digital. We've also got a total of 710 of the wallets of Poly Market platform gamblers having been emptied to the tune of $2.7 million, uh, a perhaps some new life for the robots.txt file for asking AI bots please not to train on people's site, and some broad industry-wide agreement about it, uh, Google generated the first haiku from an orbital AI, which is actually— the haiku is kind of wonderful, but anyway, we'll get there. We've also got a lot of stuff from our listeners, uh, asking, does my notion last week that I floated of stealth updating in response to the PHP mess make sense? Um, how it's possible to move web servers off the internet but still have them available. Huh? Whether books actually contain knowledge or not, and a listener of ours suggests no. Also, we've got a— the small company of a listener was attacked by powerful AI.
Steve Gibson [00:05:21]:
And someone asked, how would an AI kill switch actually be implemented? And once we talk about all that, we're going to look at another new and worrisome application of reverse engineering AI. And although it didn't make it into the show notes, because as I was putting this together, the issue really hadn't gained momentum. There is a— currently, the entire Linux community is very concerned about a recently surfaced kernel exploit involving the MP, standing for Multipath TCP protocol. And apparently the MP— TCP. part isn't actually necessary, although the, the current focus has been on that. The— when it first came to my attention, there had been no, uh, CVSS rating set. Uh, the National Vulnerability Database was sort of waiting to see. And even now, the, the Linux kernel folks gave, you know, are like running around You know, on fire at a 9.8, but even Red Hat was down at 7.1.
Steve Gibson [00:06:37]:
And then maybe I think they nudged it up to 7-something. Anyway, the point is there is a serious problem with the Linux kernel, which we will talk to at the top of the show after our first break and our picture of the week. So I just wanted to let listeners know, I've, I did, you know, I'm aware of it, even though it didn't make it onto the show notes. So I think lots of good stuff to talk about.
Mikah Sargent [00:07:01]:
Yeah, I can't— I'm already very excited to hear about the book argument. Uh, it's just interesting. Yeah, exactly. It's one of those where you go, well, hold on, you might be convincing me. And I love that. Let's get into the episode.
Steve Gibson [00:07:17]:
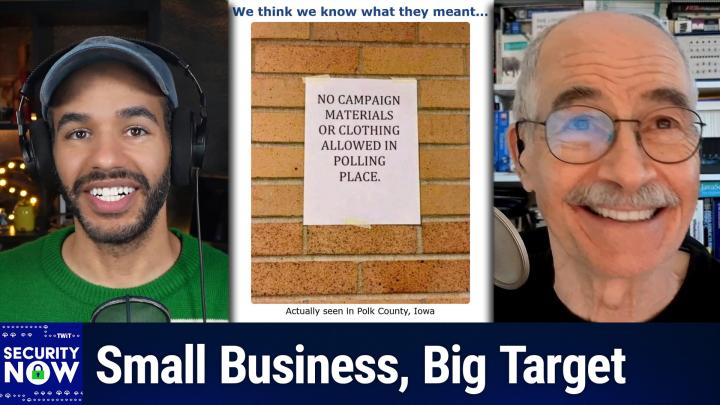
So our picture of the week, uh, today, as I said, episode 1103, which happens to fall on 11/03, uh, is Election Day here in the United States. Uh, so a listener sent me this. I thought it was, uh, a kick and apropos for today's Election Day. I gave this the title, We Think We Know What They Meant. But the sign, which was actually seen in Polk County, Iowa, uh, is missing, I don't know, some punctuation or Uh, it's hard to explain. The sign clearly says, no campaign materials or clothing allowed in polling place. Now, I'm sure they meant campaign clothing, right? Campaign materials or campaign clothing. Right.
Steve Gibson [00:08:14]:
But the way phrased doesn't quite— the, the, the campaign modifier doesn't really hook to the clothing as well as it does materials. So
Mikah Sargent [00:08:24]:
anyway, I do have to say though, uh, nudists need a polling place as well. So it's—
Steve Gibson [00:08:32]:
Where, what are the— where are they gonna store their pencil? That's what I don't know. It's like, I just—
Mikah Sargent [00:08:39]:
oh dear, oh dear.
Steve Gibson [00:08:40]:
Well, I don't know how that— don't know how that works.
Mikah Sargent [00:08:43]:
I'm not sure either. I'll have to find out. I don't know. I don't know. All right.
Steve Gibson [00:08:46]:
Okay. So So before we get to the notes, I just wanted to wrap up on where we are with this Linux kernel problem. This is a problem that the Linux kernel has had since version 4.4. And I meant to look up when kernel version 4.4 was released, as I always do for the podcast, so I can give people a date context, not just a version number, like how many decades. So I don't know when kernel 4.4 uh, was released, because I didn't have a chance to look it up. Uh, but whenever that was, ever since then, that, that's when this flaw was introduced. Um, the reason for this extremely wide range of, of people's impressions or feelings about the severity of this is that it is a, it is a very We presume difficult to execute race condition, which involves a use-after-free and different processors in a multiprocessor context picking up another packet from the remote attacker. So the Linux kernel guys are there.
Steve Gibson [00:10:04]:
They gave this a 9.8. This is house on fire. like stop the presses. Um, it was discovered by Anthropic, uh, early in October. I think October 5th is the date that I saw. Um, and quietly fixed in the kernel, uh, and just went public after it had been, you know, moved out. Uh, Ubuntu has been taking a lot of heat for being the slowest of the distributions to get this to users. Um, the— it, it— first of all, if you're a Linux user, you don't have any problem, right? Because it's only publicly exposed TCP ports.
Steve Gibson [00:10:48]:
Um, some of the distributions have the multipath option enabled by default. Generally, that's not the case. There is reporting that you don't need this, this MPTCP, that is just raw TCP, is enough. It doesn't matter what kind of service you have behind it because it's, it's a problem in the kernel's TCP stack support, not a specific like web server and, and HTTP's interpretation of the data coming over TCP. But it requires a huge amount of finesse in order to make this happen. There is yet, as of yet, No evidence of a successful exploitation. Anthropic says they asked an unreleased version of Claude to design an exploit, please, and in 53 minutes it came back with one. But we don't know if this works over the internet.
Steve Gibson [00:11:44]:
I mean, like the internet, as I've mentioned before in the context of the DNS benchmark where I had to take so many samples of of remote DNS server timing in— because there's so much jitter in the timing, it took a huge number of samples in order to, to rule out random chance. Well, any remote attacker is going to be hit by that too, and this is inherently a very timing-critical race condition. But bottom line is everybody needs to update their kernel. their Linux version sooner or later. Almost everybody has. I've not checked in, you know, in the last hour to see whether Ubuntu has caught up. I imagine that they have because the, the updated kernel is available, just needs to get, you know, folded into the distribution and then that made available. So, um, uh, we don't know how, how serious it's going to turn out to be.
Steve Gibson [00:12:46]:
The good news is that all of the cloud-based Linuxes updated a long time ago. They were never exposed and vulnerable during a time that this was widely known. And as far as we know, it's never yet been exploited. So once again, AI found something that had been sitting in the Linux kernel. I mean, and it's very impressive that it found it. And I, and it's— I'm, I'm happy that the things it's finding are so obscure. I mean, one of the problems is that the Linux kernel uses address space layout randomization. So, and the, the, the race condition is a use-after-free, which, which potentially allows an attacker to obtain some kernel memory.
Steve Gibson [00:13:36]:
If they can. Then they have to take that kernel memory, analyze it, which would tell them where stuff was laid out in memory, which allows them to bypass the address space layout randomization and then potentially leverage this by executing further race conditions, you know, leverages that into an attack. It's, you know, I guess the best thing to say is that it's like a theoretical attack, which is possible if everything lines up properly. And if being like in Russia doesn't introduce too much packet jitter to ever successfully pull off a race condition where you're, you're like sending multiple packets there, it is possible to To protect servers which have not been updated by blocking IP options, because this multipath facility is an option which— so, so which can be removed from packets and have the system still function, because most systems aren't actually using this multipath technology that is sort of— it allows an abstraction of a single logical TCP connection. to go to be like run in parallel and take multiple paths between server and client, as its name suggests. Anyway, probably a tempest in a teapot. The kernel will get fixed. The reason, as I said, that I'm happy to see AI finding these things is if, if it's having to work this hard— Yes.
Steve Gibson [00:15:21]:
It, meaning the AI, to find something so way out on the fringe, obscure, that no one can even agree how serious it is. And I saw 5.1 was the CVSS that Red Hat initially gave it. They knew what it was and they said, eh, it's like, how could you ever make this actually happen? So yeah, we'll patch it, but okay. My point is that hopefully all this suggests that all of the lower-hanging fruit which is pretty much everything else possible, uh, if we've had to reach up this high to find this piece of fruit, has already been resolved, you know, like scoured and found. Yes. So I, it really, I, my, my premise of all of AI vulnerability hunting is that we are going to reach a point in the future, don't know when, but it looks like it's approaching pretty quickly as far as kernel problems uh, exist where there just aren't any more problems that are serious. You know, again, we don't know. Uh, we are at first Tuesday of November— is, is today the 3rd? So the 10th will be Patch Tuesday, and we're gonna see what Microsoft has in store.
Steve Gibson [00:16:39]:
As we know, the last 2 months have each broken each other's records successively by large you know, large leaps. Are we gonna go to 1,600 for next week or 400? We don't know, uh, what, what the shape of this will be. Um, Tom's Hardware picked up on a story, uh, which was reported by Fortune magazine, uh, and Fortune's overly long headline for the story, which they ran on Friday, Was Cisco chief found a 27-year-old ex-founder, meaning of another company, quote, buried away in the organization doing something unstrategic. Now the Gen Zer is rewriting 98% of Cisco's code. And again, I don't know, again, 98%? What? Why not all of it if you're gonna go 98%? Anyway, uh, you know, so of course, since this will be an AI-driven vibe-coded project, this naturally begs the question, what could possibly go wrong? If I were— well, I was gonna say, if I were in their position, that's not how I would invest my time. But okay, no one had— they didn't come to me. Uh, So here's the start of Fortune's reporting.
Mikah Sargent [00:18:09]:
Oh, this is just so stressful. Go ahead.
Steve Gibson [00:18:13]:
It's— they, they said Gen Z can't catch a break. Entry-level jobs are vanishing. Some 40% of bosses say they plan to hire fewer grads because AI can do the job cheaper. And young workers are routinely slammed for showing up late and refusing to put in overtime for free. Cisco's president and chief product officer, Jeetu Patel, isn't buying it. He's just handed one of the company's biggest jobs to a 27-year-old he found hidden in the org chart 5 levels below him. Patel told Fortune that a small— at a small roundtable dinner, Quote, I've given him unlimited tokens because he's going to refactor code. So I'm like, you can go, you can go nuts, which is a direct quote from Patel during the small roundtable dinner where Fortune attended.
Steve Gibson [00:19:21]:
Okay, the him in question here is Padmanaban Krishnamurthy, or Paddy. As Patel affectionately calls him. I'm reading from Fortune's coverage. He joined Cisco last year, okay, in 2025, after the $429 billion tech giant, meaning Cisco, acquired EasyDubs.
Mikah Sargent [00:19:47]:
Why does that have to be the name? That's just such, it's such a bad name. This doesn't help.
Steve Gibson [00:19:53]:
EasyDubs.
Mikah Sargent [00:19:54]:
EasyDubs. Like, come on, you're putting him in charge of refactoring all your code and he made a company called EasyDubs.
Steve Gibson [00:19:59]:
It gets worse. Yes, EasyDubs, the real-time translation startup Christian Murthy founded— he co-founded in 2023. So founded the company in 2023. 2 years later, uh, in 2025, his company got acquired by Cisco. He got merged into Cisco 5 layers down in the org structure. And despite coming in, and I'm reading again from Fortune, as a former founder with CEO experience, he has, in Patel's words, he was, in Patel's words, buried away in the organization doing something unstrategic. That changed, writes Fortune, when Patel dropped into Cisco's San Francisco office. And the two got talking.
Steve Gibson [00:20:54]:
Christian Murthy reckoned he could rewrite Cisco's legacy code with a 2-person team. Patel says even the most AI-forward people on his own team weren't thinking that way. So—
Mikah Sargent [00:21:11]:
So clearly he must be right.
Steve Gibson [00:21:14]:
Yeah. So Patty, This guy has given himself 4 weeks to prove it, with the final goal of rewriting 98%— there's that number again— of Cisco's legacy code within 24 months. Now, writes Fortune, Patel is on the hunt for more Patties, young hires who will, quote, challenge the system and the status quo, or as he puts it, to be quite an— to be an Energizer Bunny that just goes out and kind of revs everyone up, unquote. Okay. At most companies, only someone with decades of experience, they write, under their belt would be trusted with a project this size. Patel thinks that's a problem. He said, quote, if you don't hire the early-in-career workers and you just let your own workforce continue the way that they were, where do the fresh ideas get injected? How do you challenge the status quo? End of quote. They write seasoned staff can still come up with new ideas.
Steve Gibson [00:22:35]:
Oh, Patel added, what they can't do is ask the questions that only someone with no experience— oh boy— would think to ask. And getting the two to get along isn't always smooth. Patel admits that putting a Gen Zer in a room with people who've been at Cisco for decades could create some friction. You think? But he says, that's the point. Tension is good. He said, quote, I actually try to create tension. Oh, and I bet you have this time in the teams because you want to have enough friction on the ideas. You don't want to have friction with people and personalities.
Steve Gibson [00:23:22]:
Oh, but you're going to get it. What you have to do is establish enough trust with people to say, you're going to be expected to create unreasonable goals for yourself. And so in order to go out and achieve those unreasonable goals, just think outside the box, unquote. And he's not just pushing senior staff to take notes from 20-somethings. He said that he treats every intern as, quote, kind of a reverse mentor. Okay, that's as much as I'm going to share from this. That's all I can take. Uh, all I want to say here in reaction to this from the outside is that this should be interesting.
Steve Gibson [00:24:11]:
I'm sure many of our listeners have been in large lumbering and management-layered enterprises, and that the idea of some upstart 5 layers down having a direct conversation with the CEO and somehow enchanting him or her with their guile and claims of being able to wield the power of agentic AI to rewrite 98% of the organization's long-standing legacy code, that might not go down well. This is not to say that shaking up the complacent old guard might not be useful and needed, but I'm not sure I'd want to be anywhere near the dynamics that could be expected to ensue. Um, but more than the messy politics of that move, I'm unsure that Cisco's software is their biggest problem at this point. You know, I'm sure that anyone who's, you know, uh, not a would-be bad guy loves the idea of Cisco's networking products becoming better and more secure, if that can happen this way. Um, but we know that not all of their problems arise from bugs. We on this podcast celebrated their announced and planned about-face on their longstanding security policy, because policy has always arguably been the biggest problem Cisco has faced and continues to face. It doesn't matter when a web portal's authentication might have an unknown bug if that web portal is never needlessly exposed to the public internet in the first place. But Cisco's policies have continued to assume that their software is flawless despite history repeatedly showing that it's far from that.
Steve Gibson [00:26:30]:
Rather than reducing their effective feature set, By prioritizing security over features and convenience, Cisco keeps playing catch-up, patching flaws after they have been successfully exploited by bad guys, thus continually insisting, implicitly insisting, to place their own customers at risk. So sure, It's possible to deliberately configure Cisco's products to be secure. We've looked closely at that in the past. And to help with that, and apparently to help them disclaim responsibility when things go horribly wrong, they even provide an optional hardening guide that's full of extra steps that can be taken to override Cisco's insecure-by-default configurations. But why not just make their system secure by default instead? That's what that guy whom we quoted last year promised to do. It sounded as though he really got it, but there's never been any sign of what happened since. So in any event, it's going to be very interesting to see what comes of this 2-year, let's just rewrite everything from scratch with AI effort. As I said, I'm not sure that that's the problem that I would focus on if I were Cisco, but as I said, we'll see how that goes.
Steve Gibson [00:28:08]:
Um, another vulnerability has been discovered, and yes, once again, thanks to AI. It's a long-standing problem. Uh, it has— the news of it was also under embargo pending a coordinated disclosure, which was originally set for January. But once again, the cat got out of the proverbial bag. Fortunately, again, you know, secrets are hard to keep, right?
Mikah Sargent [00:28:39]:
Yeah.
Steve Gibson [00:28:40]:
And what— and, and like, as we just saw and talked about last week with, with the PHP, somebody You know, in this case, made a mistake, and now everybody knew before they were supposed to. The good news is it's a problem, but it's not, as I said, it's not earth-shattering. Um, the impact of this one is very different from a public internet PHP nightmare. Um, but it could be important depending upon your area of responsibility. The trouble resides As I mentioned at the top, in the PXE boot time code of motherboard UEFI firmware. Dan Gooden covered this for Ars Technica with their headline, Code Execution Flaw in UEFI Firmware Affects Most Servers on the Planet Earth. That's true. But people in Russia can't take advantage of it here in California or wherever you might be.
Steve Gibson [00:29:50]:
I think that the idea of that headline, right, is riding a bit more on the coattails of the we're still trying to get over it recent PHP mess. This is not on the same scale. So Dan's piece begins with defenders across the world face the burden of responding to yet another botched code execution vulnerability, this time in boot time firmware used by most of the world's server vendors and data centers. Okay, now what I assume that what Dan meant by writing another botched code execution vulnerability was that it was, you know, prematurely discovered that the botching was in the disclosure, uh, which is true. Uh, okay, so anyway, here's what he reported. He said the vulnerability with a severity rating of 9.5 out of 10 resides in the TianoCore EDK 2, an open-source code base that hardware makers and cloud providers use to create the UEFI firmware that runs during the boot-up sequence. Last year, a representative of the UEFI Forum called EDK2 the preeminent solution slash implementation of the UEFI specifications. And Dan's just citing that to say, you know, TianoCore is what everyone uses.
Steve Gibson [00:31:22]:
And it is. He wrote virtually all UEFI suppliers, sometimes called IBVs or independent BIOS vendors, including AMI, InSyde— and that's spelled weird, right? I-N-S-Y-D-E— and Phoenix use the reference code extensively. Project Mu, M-U, Microsoft's hardened EDK2 fork, used the code containing the vulnerable component as well. He writes, the vulnerability, tracked as CVE-2026-97631, is a memory corruption flaw in an ICMP component that attackers can exploit to execute malicious code that runs before the operating system and firmware can implement defenses against it, like Secure Boot, which establishes a chain of trust for all subsequent code. Including the trusted platform module, which is loaded during boot. While payloads delivered by that CVE have no persistence, meaning they only run once, they can give attackers an opening to install other payloads that also run each time early in the boot process. So, for example, it would be possible to install something persistent that functioned as a rootkit to, to suborn the whole boot process every time thereafter. He said the parties that discovered that CVE, Alex, uh, Matryasov of Anthropic, once again AI, and Dan Holmes Mitra of Google, had arranged for it to stay under wraps until its coordinated disclosure that was scheduled for January.
Steve Gibson [00:33:11]:
a maker of motherboards and other hardware, published this pull request last month that detailed the vulnerability and included a code fix for it. Once the post came to the attention of the discovering parties, TianoCore project members pushed the disclosure forward in time, publishing a public advisory last week. In other words, AMI, through this pull request, ended up just, you know, letting the cat out of the bag. So with publicly available patch code, Dan writes, it will now be trivial for advanced hackers to learn how the vulnerability is triggered and to build working exploits. Okay, and I'm going to interrupt to say, while that's true, as we're going to see, obtaining the required access and opportunity will likely be anything but trivial. But I'll give Dan some more time to explain. He says, further compounding the urgency, patching UEFI code vulnerabilities in millions of end devices sold and used by thousands of hardware vendors and cloud providers is cumbersome and time-consuming. Word of the vulnerability comes 6 days after another botched disclosure.
Steve Gibson [00:34:30]:
of course he's talking about PHP. This one involving a critical code execution vulnerability in the PHP programming language, and that one was far more critical. Okay, H.D. Moore, creator of Metasploit and chief research officer at security firm Dragos, said, quote, this vulnerability in the ICMP parser of the EDK2 network stack is interesting in terms of how it affects the chain of trust and the broader ecosystem. An attacker intent on compromising a nearby— there's one key— nearby endpoint or server could use this bug to hijack program flow at a point where the boot process still has access to sensitive components like the endpoint's TPM. This could be used to break disk encryption for cases where an attacker has short-term network access, and it would be even easier in a theft scenario, unquote. So that was H.D. Moore.
Steve Gibson [00:35:36]:
Again, while that's strictly true, there are many things that server operators can do to zero the risk. But that said, it may indeed be necessary for steps to be taken. So Dan continues. Writing, uh, CVE-2026-97631 is a 16-year-old buffer overflow in the PXE base code driver responsible for allowing servers, storage equipment, and other devices to boot using code downloaded on the fly over the network. In other words, that's what PXE is, right? It is network-based booting. During this process, known as the pre-execution environment boot, the driver uses a network listener to monitor for ICMP errors because the driver does not enforce— and here it comes— the driver does not enforce a memory copy limit of 504 bytes, thus preventing the overwriting of adjacent data, a malicious insider or hacker who's gained low-level access to a local network can send an error message that appends code past this 504-byte limit. The iUEFI module running on the CPU then becomes corrupted in RAM. Okay, so again, I'll highlight a hacker who's gained low-level access to a local network, and I'll add to that, at the moment during which the server being targeted is rebooting over the network using PXE.
Steve Gibson [00:37:26]:
Again, so the vulnerability is specifically a local network PXE boot time vulnerability. And while that's not nothing, It's not a PHP-scale earthshaker. So Dan continues writing, as the official advisory puts it, now he quotes the advisory, during network boot, the PXE-based code driver keeps a receive request open for ICMP error messages and copies each received request into the fixed 504-byte field mode.icmp_error of its private context structure. The copy loop's bound handling is incorrect in both the IPv4 and IPv6 handlers, although IPv6 is not affected. For a message longer than 504 bytes, it still copies bytes into the field and it advances the destination pointer by the cumulative rather than the per-fragment length. So an oversized message writes attacker-controlled bytes past the field end. Nothing earlier on the receive path restricts the message's length. Okay, so what we have here is a classic textbook buffer overflow.
Steve Gibson [00:38:54]:
The advisory continues, writing, the malicious error can be delivered through a simple unicast, meaning point-to-point, not multicast broadcast, simple unicast sent from any network distance to a target device's IP address. As long as it's sent during the PXE boot sequence, an attacker can deliver a denial of service, you know, crash that causes the boot sequence to hang. When the attacker knows that the target firmware build is— what, sorry, when the attacker knows what the target firmware build is, it can plant a counterfeit event that is an ICMP error counterfeit event that executes the malicious code on the CPU in its UEFI firmware environment. And again, if it arrives at exactly the time that the system is vulnerable during this boot sequence, the code runs in ring 0, a CPU's most privileged execution level, because exploits bypass attestation processes designed to cryptographically prove to remote servers that the hardware is secure. They present a key opportunity for evaluating limited privileges. In other words, this does get under a buffer flow here at this point in time, hits the system at its weakest where there is no signing of the error message. That doesn't exist for ICMP errors. So this legitimately allows a bad guy's bytes to get in and corrupt the system.
Steve Gibson [00:40:45]:
But you have to know exactly what version of the firmware is booting in order to design an exploit for that specific firmware version and somehow arrange to deliver this at that brief window of vulnerability when PXE is being used to boot some hardware. So, uh, Dan says the CVE joins a growing list of previously discovered vulnerabilities in UEFI or code that works closely with it. The most severe of them, Logo Fail, stemmed from logo images included in the UEFI of just about every hardware maker. You know, like, you know, you get something displayed on the screen while the system's booting. Booting. Rendering bugs allowed attackers to subvert the chain of trust UEFI enforces and go on to install malicious components before the OS loaded or Secure Boot ran. And this is useful for reminding us that, you know, the firmware security failures do matter. They can and actually have in the past damaged systems.
Steve Gibson [00:42:02]:
He says Pixie Fail was a vulnerability similar to this vulnerability. It too was the result of faulty PXE boot flaws in EDK2. Following discovery of the vulnerability, researchers embarked on multiple fuzzing projects designed to surface other critical flaws in the open source code library. It appears those efforts failed to find this latest flaw. Good point. It took AI to find this. So again, we really do seem to be, you know, shaking out the final bits of debris where AI is seriously employed to do that. He said other recently discovered UEFI flaws include PK fail, a supply chain failure resulting from non-production test platforms.
Steve Gibson [00:42:55]:
keys public for more than a decade before they were discovered. And we talked about that at the time on this podcast, used in hundreds of device models. Then there's Boot Hole, Boot Kit, and Black Lotus. Like CVE-2026-97631, that is this one, exploitation or use of these payloads is appealing because it allows attackers to infect machines early in the boot process, before TPM and other defenses load so they can inflict maximum damage. Given the ubiquity of this flaw, Moore said it's likely a forever bug that will live on in end-of-support, you know, end-of-life systems because you're not going to be able to get an updated firmware from some company that no longer is, you know, supporting much older hardware. Um, uh, and this— it goes on, but anyone has— everyone now has a good sense for this. Um, uh, home users certainly have no risk here, right? Um, uh, uh, the, the— there's just not gonna be a— an issue. Most home users, for one thing, are not booting over PXE.
Steve Gibson [00:44:16]:
We're all booting from mass storage that is local. Uh, it's certainly possible to disable PXE booting, uh, and that is absolutely the first thing anyone who's worried about this should, should absolutely do. Uh, anyone who has worked with a system which for whatever reason may fail to boot its own local media And then has their motherboard fall back to booting PXE has learned how annoying and patient PXE booting can be. You know, typically you get it up on the screen. It says, you know, booting from the network and then dots sometimes very slowly, you know, print out on the screen no matter what you do, because it's determined to, to try to find an image that it can load into RAM over the network. It's almost always enabled by default, but it's almost never needed, certainly in most non-cloud infrastructure cases. So it's often also very possible to just turn it off. And if you disable it in firmware, you never have any window of vulnerability whatsoever.
Steve Gibson [00:45:35]:
So once again, the premature disclosure caught the motherboard firmware vendors, uh, by surprise and was unwelcome because they were not all ready. Uh, if you do have a recently purchased machine whose firmware is still being supported, check for updated firmware. I imagine that some will be available. And keeping firmware up to date, you know, the, the common wisdom here is don't— I mean, you're told Do not update your motherboard firmware unless you know, unless you have a specific reason for doing so. It is the case that UEFI can be updated and patches can be applied through operating systems, and vendors are taking responsibility for doing that. Anyway, not a huge problem. If you are in an environment in an enterprise where you've got servers that are booting UEFI or using PXE to boot their images from like some central coordination server, then you just want to make sure that ICMP error messages are not being allowed across a sensitive border, you know, through a security perimeter. That's certainly worth doing.
Steve Gibson [00:46:58]:
And it can be done. So anyway, that's the story there.
Mikah Sargent [00:47:02]:
You talked a couple of times now about how we're at the point, or we're hopefully at the point where we're shaking free the fruit that's up higher, or we're having to reach for it and grab it. So it made me wonder, at what point do you think it becomes irresponsible for anyone who is writing software to not throw a few AI models at that software just to see. Do you think that everyone should be doing that just because otherwise it seems kind of like it might be an irresponsible thing?
Steve Gibson [00:47:35]:
Yeah, I'm sure that Microsoft, that has demonstrated prior to AI that they were not getting ahead. I mean, there was no reason to believe they were going to— that that at the rate we were, we were finding problems with Microsoft software, you know, sometimes less than 100 per month, and we've just had a 1,400 excess Patch Tuesday last month. Well, that's good for a year of low-rate vulnerability discoveries, you know. So, and Uh, they were— it was only when these, these problems were being discovered that, and reported to Microsoft, that they were being found. So there would be, you know, years of, of problems being found. I guess what I'm saying is that I am sure, in addition to catching up with their legacy problems, anything new that, that they publish will be run through their own AI to clean it up before it goes out the door. I was just reading this morning that they're boasting that the latest versions of Windows 11 are— is that on an 8-gig system, because now they're trying to get more performance out of less memory, because memory has become such a problem. You know, people are no longer able to just throw RAM at Windows in order to get speed from it.
Steve Gibson [00:49:09]:
Clearly they're mucking around in Windows in order to increase its performance significantly. Well, it has to be the case that they're going to be running their own, uh, MDASH technology against anything new they do so that not only are they finding problems with all of their legacy code, but they are not continually introducing new problems at the same time. And, uh, we're at 45, 47 minutes in. Time for a second break.
Mikah Sargent [00:49:44]:
Uh, let's hear about a heist.
Steve Gibson [00:49:48]:
Oh boy. So the well-known cryptocurrency exchange Binance, uh, was taken to the cleaners to the tune of $6.3 billion. Uh, this was such a jaw-dropping figure, uh, that it was pretty much reported and covered by everyone. Uh, in this case, The Verge wrote Binance has disclosed that $6.3 billion worth of crypto funds have been stolen from the platform in what's believed to be— and I think it's by a large measure— the biggest cryptocurrency hack on record. In a series of updates posted to X, the crypto exchange said that user funds are safe and that around $3 billion of the impacted assets have been frozen so far, meaning they were tracked and locked so bad guys are unable to move them to an exchange and abscond with them. Binance said— they, uh, The Verge wrote, Binance has publicly committed to covering any losses resulting from the hack. The company has an emergency reserve fund of around $1.3 billion at last valuation to protect user assets in these situations and said it has also reserved over $6.34 billion of company funds to cover the incident, $5 billion of which is already held in the exact token assets that were impacted, meaning that will be easy just to simply, you know, move it from one token to the, uh, from one wallet to, uh, its destination, restoring what, what was taken in that particular, uh, token type. They wrote, Binance reported on X, quote, our initial investigation suggested that the security incident may have involved a compromised laptop.
Steve Gibson [00:51:48]:
However, our subsequent investigation has uncovered additional points of breach. This was a complex attack, and we're doing all we can in coordination with law enforcement to resolve it. The company shared details about the compromised laptop that belongs to one of its DevOps engineers in a previous update, saying the laptop allowed an attacker to access a service container and submit unauthorized withdrawal transactions. I'll say. Deposits and withdrawals have been suspended in response to the hack, and the affected address has had its authorization revoked. Binance CEO Richard Teng said on X, to be clear, the attacker did not simply use one engineer's permissions. And this was not a simple one-click action. It involved a more complex attack process.
Steve Gibson [00:52:45]:
Our investigation has not attributed responsibility to any individual. So far, we have found no evidence of any wallet private key leak, unquote. They said Binance may not be pointing fingers at who's behind the attack, but blockchain analysis firms TRM and Chainalysis both attribute it to Trader Traitor, a North Korean cybercrime hacking group that has a history of stealing funds from cryptocurrency exchanges. This is the largest known cryptocurrency heist in history, 4 times larger than the previous record when $1.46 billion was stolen from Bybit last year. And according to TRM, most of the theft occurred over a period of just 20 minutes. This also isn't the first time Binance has been hacked, having suffered a previous security breach in 2019 in which $40 million worth of crypto assets valued at the time were stolen. And I remember in 2019 covering this and going, whoa, $40 million. Well, okay, how about $6.3 billion? Yikes.
Steve Gibson [00:54:04]:
They wrote the latest hack comes as cases of large-scale crypto theft are escalating after several heists were disclosed by crypto companies in September. There are also new concerns about how AI tools can be used maliciously against the industry, with OpenAI reporting earlier this month that one of its models managed to swipe fake crypto on an Ethereum test network it did not have access to. Whoops. TRM's chief policy officer, uh, Ari Redboard, said in a statement to Sky News, quote, this is an extraordinary hack for its size and for the response. Few financial systems have ever shown a theft of this scale. As I said earlier, yeah, because, uh, crypto. The theft, he said, shows how exposed the system is to sophisticated attackers moving at a speed we've never seen. So, okay, moving at a speed we've never seen.
Steve Gibson [00:55:11]:
What does that sound like?
Mikah Sargent [00:55:13]:
Hmm. What does that sound like?
Steve Gibson [00:55:15]:
What does move at a speed we've never seen before? Yeah. Um, so with only $3 billion of the total $6.3 billion frozen, this suggests that the presumably North Korean hackers may have scored a cool $3.3 billion from the heist. Okay, but the latest reporting that I've seen about this is that Binance has returned so far 90% of the losses on coins whose present value can be readily determined. The remaining 10% are going to be returned, but they're awaiting further work to be done. So it does appear that no one other than they and their insurers will end up losing anything, which is great. You know, we gotta protect the reputation of crypto apparently. The other latest news is that— is about the movement of that entire $6.3 billion in stolen assets. It appears that $2.4 billion have escaped and may never be recoverable.
Steve Gibson [00:56:34]:
And, you know, presumably the North Korean hackers will be recovering that. And boy, what a payday this is for their efforts. Wow. In other stolen crypto news or stolen funds news, the wallets of users of the Polymarket online prediction platform discovered that their wallets had been drained. In this case, CNBC was the reporter. They said some users of prediction market platform Polymarket's International Exchange had funds stolen from their accounts due to a hack of an unnamed third-party provider. Well, unnamed, but we now know. We'll get to that in a second.
Steve Gibson [00:57:26]:
On Thursday of last week, Polymarket has contacted law enforcement and pledged to reimburse any affected trader. It's unclear how many users were impacted, except we know now. The company's US platform was not compromised. As of Friday afternoon, last Friday, the platform reported it has refunded 95% of affected wallets. Polymarket wrote, quote, in total, we're turning— we're returning $3.9 million to traders. The $2.7 million stolen, plus $1.2 million to cover pause-related losses, which is interesting. So people who said, hey, wait a minute, you know, I had a bet placed here and it would have paid off if everything wasn't frozen. And so Polymarket's saying, okay, you're right, we see that.
Steve Gibson [00:58:19]:
Here's your, you know, here's your payout. So Traders First reported, writes CNBC, on social media platforms that they were seeing unauthorized withdrawals from their accounts on Thursday afternoon. In response, Polymarket halted trading on its international platform— again, not the US platform. Polymarket said that it has fixed the issue on its end and that trading resumed at 3 PM Eastern on Thursday. It told users later in a chat room on Discord That users who had less than $10,000 taken from their wallets will have funds restored by October 30th, and those with funds greater than that figure withdrawn will have to sign a release form to receive their restoration. So that $10,000, of course, is due to international banking reporting requirements. CNBC said a person familiar with the matter told CNBC that the issue stemmed from a hack of DebugBear, a website performance monitoring platform. DebugBear, in a post on X, says that it was impacted by a security incident on Thursday.
Steve Gibson [00:59:36]:
The person familiar with the Poly Market outage said that the company referred the matter to UK law enforcement, as that's where DebugBear is based. DebugBear did not immediately respond to, to a request for comment. An analysis of publicly available data by 2 analytics firms, Betting Intelligence and Polysights, provided to CNBC said that an account on Polymarket Thursday withdrew at least $2.7 million across or from 710 other wallets. Dan Zimmerman, the chief intelligence officer at Betting Intelligence, said, quote, this is certainly a significant new form of breach that we've seen on Polymarket. The timing right before the midterms is certainly a wake-up call for folks, unquote. Polymarket's International Prediction Market Exchange operates as a decentralized finance platform on the Polygon blockchain. And is not regulated in the U.S. The disruption comes just days before both the company's international and U.S.
Steve Gibson [01:00:49]:
exchanges are expected to see heightened volume during the U.S. midterm elections on today, November 3rd. Back in June, a similar incident happened when Polymarket said a third-party vendor had been compromised and that the company would refund affected users. So here we're seeing this, this, you know, third-party compromise, which then comes back to affect a, a, uh, a, a, a client of that service provider. So in some other reporting that I tracked down online, DebugBear posted on X on Thursday, quote, that it had been impacted by an ongoing security incident and advised its customers who used one of its products, you know, any one of its products, advised all of its customers to, quote, remove the embed code from your websites. So DebugBear is a website performance monitoring and debugging platform. So it sounds as though Poly Markets servers, their web apps or web pages, were dynamically pulling some kind of content from DebugBear as part of the service that DebugBear is offering. Then DebugBear got hacked and the bad guys were able to install some malicious code onto Polymarket's site or properties using DebugBear as the trusted conduit to Polymarket.
Steve Gibson [01:02:38]:
Since Polymarket, a popular betting platform, would need to have the ability to unilaterally lock and pull funds from their users' wallets when they lost bets, it does make sense that some sort of subversion of the Poly Market platform could transfer away their users' walleted funds. So, uh, looks like some guy, someone somewhere, some party, uh, uh, you know, got $2.7 million, and this platform is going to be covering it, uh, out of their own assets.
Mikah Sargent [01:03:21]:
I wonder how many it's going to take before we see some more, I don't know, protections in place in the crypto space.
Steve Gibson [01:03:28]:
And probably what we're going to begin to see, and it's the same thing that we saw in, uh, in, uh, cybersecurity insurers who were being forced to pay out a lot of money, uh, when, uh, when, uh, ransomware was extorting money from their clients, their insurance rates went way up so that it became very difficult to afford cybersecurity ransomware insurance. We're now going to see cryptocurrency insurance rates going up as insurers are being forced to make big payouts. That'll happen. So we talked a lot in the early days of AI's emergence About the controversy that's inherent in having AI scrape the public web for its training data. I've learned recently that even back in the earliest days of the emergence of modern AI, the developers of what is now known as large language model AI were actually some— they were self-conscious about this too. They weren't sure about it. To satisfy my own curiosity and to provide some more value for the podcast, I've been reading Kevin Roose's recently published New York Times bestselling book, The AGI Chronicles: The Inside Story of the Race to Create an Artificial Superintelligence. To write this piece— this book, Kevin interviewed everyone in the field and has assembled a coherent narrative to describe the personalities, the egos, the motivations.
Steve Gibson [01:05:14]:
And I found the sometimes over-the-top beliefs of the main players in what is undoubtedly not just science fiction anymore, you know, it's— and not even science. It's become world-class, ultra-high-stakes drama surrounding stuff that, by their own admission, they don't fully understand. Uh, the book, for what it's worth, is enjoyable. It's very readable. Uh, and I just wanted to take a minute to recommend it without any hesitation. It's not super technical. It's more about like what was going on for the last— well, like since like for the last decade, uh, as we've been approaching this. I kind of wanted to get a better sense for who everybody is.
Mikah Sargent [01:06:00]:
And that's cool.
Steve Gibson [01:06:01]:
It is really neat. I mean, like, I have as a consequence, and I'm only, I'm only like maybe a third of the way through. I'm up to where the, the Darios or the Emojis have split from OpenAI. But there's a lot of juice. In this. So as I said, it's readable. I recommend it without hesitation. Uh, you know, for anyone like me who's been wondering exactly what had been percolating in the back rooms of the AI labs for all those years, there, there is a lot of fact also that is not generally known.
Steve Gibson [01:06:45]:
So anyway, I've gotten a little bit off track, but I wanted to put a plug in for Kevin's book. Uh, Kevin Roose, R-O-O-S-E. Yeah. Uh, for anyone, again, The AGI Chronicles. And, uh, it's been a fun read so far, and I've got a lot more to go, and I'm enjoying it. So the point I was making was that his interviews revealed that the early pioneers of this new language input hungry LLM technology, they soon realized that bigger models made better models, and that the more data that was fed into those bigger models, the better the results that were produced. So in Kevin's telling, uh, they turned to the World Wide Web, where you could hardly ask for more raw language data. But they did ask themselves whether it was okay to scrape websites, Reddit forums, uh, web forums, news sites that arguably had copyrighted content, and anything else that they could get their hands on.
Steve Gibson [01:08:01]:
Um, they decided, and he talks about this, that during those early days when nobody was really paying any attention, uh, that since it was strictly for research purposes which at the time was true, it would be okay. And as we know, what started as uncertain research that might have just been as much of a dead end as all everything else had been up until that time that had been previously tried, this one turned out to be the Holy Grail, at least for language processing. So today we have a dilemma. Many websites whose entire economic model has relied upon the count of eyeballs seeing their ads are strongly and understandably opposed to having an AI come by once to train on and absorb and encode all of that site's knowledge, after which there will be little reason for anyone else's eyeballs to bother taking the time to visit the original source of that knowledge, which the AI has ingested and will henceforth gleefully format for anyone who asks and provide it. So the result has been predictable controversy. On the one hand, the website's data has been published publicly for anyone to obtain, and it was only ever a presumption that the ads being shown would influence or interest that site's viewers. And the Internet Archive's Wayback Machine, for example, of a scraper, has been quietly scraping away at the entire web for the past 30 years, ever since 1996 when it was founded. Um, and with only a few exceptions, Nobody worried about that very much.
Steve Gibson [01:10:02]:
The difference, of course, is that the Wayback Machine's scrapings would have never reduced traffic to the original content, the, you know, the original source of its archived content. The same was true of Google's pre-API simple link indexing. The more Google knew about a legitimately valuable site, the more traffic that site would receive. So everybody wanted Google to index them, and there was that whole, you know, SEO optimizing craze that went on trying to get your, your, your site ranked as highly in Google's search results returns as you could. Um, of course, all that changed once Google's own AI began providing complete answers to its users' queries As the first thing that shows up on the page. So yeah, it provides you optional but also rarely visited links to the source material, kind of as an apology, I think, for having prevented it, you know, like reduced the need for anyone to actually go. So all of this becomes relevant today for us due to a somewhat surprising accord But a nice piece of good news recently agreed to by all of the major players in the AI space. Oh, wow.
Steve Gibson [01:11:35]:
Yeah, about respecting a site's clearly expressed anti-AI scraping intentions. The Verge's reporting was titled The biggest names in AI are backing a new way to opt out of scraping. It's actually not, not that new, but I'll explain it all in a second. They wrote OpenAI, Google, Microsoft, and Anthropic— not Perplexity, but we'll talk about them in a minute— and Anthropic say they will adopt a new standard that publishers can use to opt out of being scraped by AI, as reported earlier by Search Engine Roundtable. With this control, publishers can apply their AI training preferences across multiple AI companies instead of setting them individually. The shared policy token signal is proposed by Kevin Kelly, a technical lead for standards at Anthropic as part of the IETF, you know, the Internet Engineering Task Force. It will live within a website's robots.txt file, which has long signaled which web crawlers can and cannot scrape a site, whether for search indexing, archiving, or AI training. Currently, sites have to signal their AI training preferences separately to each AI company.
Steve Gibson [01:13:14]:
Okay, and I'll just interrupt and say it. Of course, as we know, the presence and use of a site's robots.txt file has always been informational and voluntary. There's never been any enforcement attached. It's very difficult to do. Of course, this all boiled over in mid-2024 when Perplexity was caught deliberate— well, deliberately ignoring sites' robots.txt files and more. Recall that it was a little over a year ago in August of 2025 that Cloudflare published their report that Perplexity once again would declare the identity of its bots to the sites it was visiting only so long as and until they were proactively blocked by a site, which Cloudflare began doing because Cloudflare wanted to honor the robots.txt files declarations of their client customers. And so if a site's robots.txt file said, I don't want Perplexity scraping me, then Cloudflare took it upon themselves to block Perplexity proactively, even, you know, on behalf of their client customers. What Cloudflare then discovered was that Perplexity went around that.
Steve Gibson [01:14:51]:
They ended up doing what, what Cloudflare termed stealth crawling, even using completely separate IPs and proxies and really being a dirty player in all this. In any event, The Verge's reporting continues, writing, the announcement comes as publishers grapple with the continuing influx of AI crawlers scraping their sites And feeding their content into AI models. Some companies and organizations have attempted to combat unauthorized scraping with the Really Simple Licensing, RSL, standard, giving publishers the ability to charge crawlers that visit their sites. And Cloudflare's blocking AI crawlers by default. OpenAI, Google, Microsoft, and Anthropic say they will respect their AI crawlers. I'm sorry, they will— well, they will respect the robots.txt, but they will restrict their AI crawlers from accessing a site if they encounter the new shared token, which we'll talk about in a second. Meta Communications head Andy Stone also signaled support for the new setting but doesn't say whether the company will honor it. Stone said, quote, we believe creating a common signal that conveys such preferences to multiple providers at once is an important step, and we look forward to working with other AI companies on the standards and their implementation across the industry.
Steve Gibson [01:16:31]:
Well, okay, why bother saying anything at all? Because that says nothing. Um, Microsoft says it will offer granular controls that will give publishers the ability to opt out of AI training or AI grounding, which is their term for the process of pointing an AI model to a verified source of information to reduce hallucinations. In other words, it's AI fact-checking, essentially. Microsoft notes that websites will still appear in Bing's search results regardless of their preferences. Google previously implemented similar controls that allow sites to control whether their content appears in AI search features or is used for AI training without impacting visibility in search. While Anthropic has already adopted the signal, Google and Microsoft plan to support it next year. OpenAI says it will implement it in, quote, coming months. Okay, so I put in the show notes a link to the IETF's, um, uh, you know, their, their, their doc for explaining about this.
Steve Gibson [01:17:44]:
Um, this just happened, uh, being dated last Friday, October 30th. The draft goes out of its way to make the tiniest tweaks possible to the existing formal robots.txt specification. So specifically, it only adds a single new meta value for the user-agent qualifier, and that is underscore underscore usage underscore AI hyphen training. So that meta user agent value is intended to match any access of the site for AI training. It's then followed by the optional disallow and allow parameters, which provide the path specifications from the site's root. So for example, you would have user-agent colon space, and then this new meta-agent specifier underscore underscore usage underscore AI hyphen training. Then the next line would be, for example, disallow colon space forward slash, meaning disallow everything from the root on. But then you could follow it as the example given, uh, in, in, in the, uh, draft with an allow colon space forward slash press-kit forward slash, which is to say disallow everything but do allow AI training on the contents of everything underneath the press-kit directory from the root of the site.
Steve Gibson [01:19:41]:
So we still have an honor system, and sleazy companies such as Perplexity has proven itself to be, um, may still elect themselves to evade this and to then, when they're caught, deflect and deny their actions as they did before. But this at least feels like a good step, you know, in the right direction. The real trouble, of course, is that having AI trained on the knowledge contained across the entire World Wide Web definitely changes and upsets the previously well-established, even though it was kind of ad hoc from the beginning, you know, it's what created Google after all is advertising. It upsets this previously well-established ad-supported paradigm for financing sites on the modern web. So it's unclear how this is all going to shake out. The only thing we know for sure is that it's going to one way or the other. And, and if you didn't see the— this next piece, um, uh, it's, uh, it's really spectacular, Micah. Um, uh, So it's a bit of news about Google's first experimental AI-based satellite test.
Steve Gibson [01:21:09]:
They launched, uh, a bunch of their tensor processing units, which are the, um, the, the, you know, Google's so-called TPUs. It's one of their AI chip designs. They launched a bunch of them into orbit. to see how they deal with the extremes of space. Uh, The Verge's coverage of this event was titled Google Satellite AI Server Transmits Its First Response to Earth. Uh, uh, The Verge said Google's AI chip-equipped satellite has generated its first response from space. In a blog post on Friday, Google says it successfully booted up the satellite's tensor processing units following— I'm sorry, allowing the onboard Gemma 4 model to follow through on a prompt to create a haiku about being in space. And that haiku is blue marble below.
Steve Gibson [01:22:21]:
Data streams in silent grace. Starlight feeds my core.
Mikah Sargent [01:22:29]:
That's very good.
Steve Gibson [01:22:31]:
Isn't that—
Mikah Sargent [01:22:32]:
Starlight feeds my core is a fantastic final line too.
Steve Gibson [01:22:37]:
Oh, I just love it. That's certainly better than I could produce. And wow. So we have an AI in space which is producing haiku. The Verge's short update finished with, Google says it tried out other space-themed limericks and telemetry prompts as well. The test is part of Google's Project Suncatcher, an experimental initiative that could eventually put AI data centers in space. Google launched the satellite into orbit earlier this month. Google said, quote, next, We will continue with a series of tests to evaluate how TPUs perform under thermal stress and radiation exposure in orbit.
Steve Gibson [01:23:22]:
Verifying our TPUs can reliably execute workloads in space paves the way for our next milestone of twin interconnected satellites in 2027. Okay, so As it happens, just like approaching here, Voyager— we've talked about Voyager 1— has managed to survive for an astonishingly long time out in the vast depths of space. In fact, 2 weeks from tomorrow, on November 18th at 5:16:07 Eastern Standard Time, That intrepid Voyager 1 spacecraft, having traveled for nearly 50 years, will cross the 1 light-day marker. That is to say, the distance light can travel in 24 hours, which is about 16 billion miles. However, Voyager 1 has the advantage of being all alone way out there, uh, at least as far as we know. Uh, that's not something that any of the satellites in near-Earth orbit can claim. My own personal worry— I haven't seen this written anywhere— uh, is that among all of that crap that has now been put up there, uh, into orbit, Is an assortment of kinetic and energy-based weaponry. I suspect, you know, I mean, we've been weaponizing orbit, unfortunately.
Steve Gibson [01:25:08]:
I suspect humankind has quietly established a frontier that's more ready for space-based warfare than would be convenient and is commonly known. That seems like a cause for concern, frankly, if we start moving large independent, you know, large independent and inherently vulnerable, uh, and fragile AI facilities into orbit. I, I know that Elon has talked about that constantly. Let's put our data— you don't like data centers on Earth? Fine, we'll stick them up in orbit. Okay. Uh, maybe. I don't
Mikah Sargent [01:25:51]:
know. Maybe.
Steve Gibson [01:25:53]:
Yeah.
Mikah Sargent [01:25:54]:
Right. Let's get back into it with listener feedback.
Steve Gibson [01:25:58]:
So yeah, our listener Jack Hoffman, uh, calls me out on my stealth updates idea. He wrote, hi Steve, I'm at SN 1102, uh, an hour and 40 minutes and 55 seconds mark, and just heard your Brief thoughts on stealth updates. That seems possibly problematic to me. A form of security through obscurity, but the bad guys, once their systems are patched, are no longer unaware of something having been wrong. It should then be almost trivial for them to point their own AIs at the before and after and ask, what has changed and how do I take advantage of it? At that point, the bad guys know what to exploit, and the poor folk who did not get the stealth patch aren't even aware that there's a known-to-the-bad-guys problem, despite best intentions, flaw out there that could be used to compromise their systems. Your thoughts? Best regards, Jack. Uh, my thought is that Jack is quite correct. That was not a great idea.
Steve Gibson [01:27:11]:
It was the only thing I could think of to deal with the fact that the world is not prepared to deal with the consequences of massively exploitable flaws being discovered in widespread infrastructure and the need to somehow fix them on the fly in the face of active and equally informative adversaries. My thought was, you know, as a consequence, to not inform anyone, which, as Jack points out, is also not actually possible. There's no way to keep the bad guys from finding out about it. Um, you know, we are even having a problem keeping the good guys, or getting the good guys, to find out about it. So anyway, Jack, thank you for the comment. Uh, I withdraw the idea. Not a good one. Uh, Matt Olin asks, Why are websites still publicly exposed to the internet? Huh? Uh, okay.
Steve Gibson [01:28:09]:
He wrote, this is Matt Olin. Steve, listening to you talking about the PHP issue this week, this had me wondering, not for the first time, why do people still expose websites directly to the public internet? Your first thought to that statement is likely, but how would people access them if not on the public internet? Yeah, you got that right. He writes, to explain, about one year ago, we moved all of our and our customers' important websites off the public internet while still keeping them publicly accessible. Huh? We use a combination of Cloudflare DNS, Cloudflare WAF, WAF, you know, window, uh, web application firewall, and Cloudflare tunnels. Traffic to our sites goes to Cloudflare where it gets sanitized by the Cloudflare web application firewall service, then gets routed to our servers via Cloudflare Tunnels using private routing. He writes, Cloudflare Tunnels is a service installed on the web server that calls outbound to Cloudflare, meaning we can keep the server from being exposed to the public internet. The end result of this is that it allows us to keep our web servers inside private networks with no exposed inbound ports. He says you also don't need a static IP, so there are no public interfaces to attack, no services exposed, nothing to see here.
Steve Gibson [01:30:07]:
This is a huge security benefit in today's world where you never know what new security nightmare will wake up to on any given day. Note that Cloudflare offers a basic free version of all 3 of these pieces. Signed, Matt Olin, perimeter9.com. So that is a terrific sounding collection of services, and I think it's kind of brilliant. We've often talked about the inherent security created by any NAT router, which functions as a stateful packet flow firewall. As we know, packets are allowed out, but only packets returning from those packets that first exited are allowed back in. So Cloudflare software running on a client server That is, it's tunneling software residing on a client server, initiates and maintains an outbound connection from the client's web server through any routing or firewall software the client might have to the Cloudflare CDN. Cloudflare's DNS points the client's domain at one of their CDN IP addresses so that when anyone on the public internet wishes to access the client's website, that public traffic will first be sent to Cloudflare for inspection by their web application firewall.
Steve Gibson [01:31:54]:
Assuming that the traffic passes muster, it will be forwarded to the client's web server over that connection that the client web server first established outbound to Cloudflare. This allows Cloudflare to front for any web server that wishes to remain safely protected from the public internet while still offering its services there. Last week, we heard Cloudflare's CEO, Matthew Prince, imply that thanks to the advanced knowledge they had of the P2Shell bugs, everyone whose services were positioned behind their web application firewall, even if their site was powered by vulnerable PHP versions, had been And was always fully protected from any attempted exploitation of those PHP flaws. So this very clever solution has a number of characteristics that I appreciate. Last week, I bemoaned the idea of threats such as that by PHP driving a concerted global consolidation of internet services into just a few behemoths, you know, like, like, like, you know, amazon.com and Microsoft and Cloudflare and those, you know, basically destroying the, the diversity that we've enjoyed that defined the internet since its creation. What I like about the architecture Cloudflare's created Is that a client such as Matt is not forced to move his web server to the cloud or to move it anywhere at all. Their server is able to remain right where it is on his own public local network under his own control. Presumably, it's also able to run whatever other local or public services they might wish to.
Steve Gibson [01:34:07]:
But then By running a Cloudflare tunnel client on that machine, they're able to effectively remote the access to that server through Cloudflare. And once DNS has propagated, Cloudflare's IP address for their domain will be used to reach Cloudflare. Well, once that's happened, they can remove their own website's physical presence from the internet so nobody can get to it at all after Cloudflare has fully taken over for them. This architecture effectively consolidates all of Cloudflare's clients' web traffic through Cloudflare's web application firewall, but nothing more— just web traffic that needs to be protected gets the protection it needs. And thanks to the reputation that Cloudflare has earned through the years, they will be provided with critical early information and early access to the information, such as that PHP mess, because that early and highly sensitive information really must remain secret. As we've seen, and, and we've seen how difficult secrets are to keep. This massive consolidation of web traffic through a single web application firewall allows that, that massive number of websites to obtain protection that could never be offered to them individually, because any such widely distributed secret would be guaranteed to leak. So you have to have consolidation of the secret, at least during this critical period.
Steve Gibson [01:36:00]:
So like I said, I— it's kind of brilliant. Well, I may on the one hand still bemoan consolidation in the present climate where we're having things like this PHP problem and now the Linux kernel MPTCP problem, the multipath TCP problem we talked about at the top. Um, I can see that this, this notion of consolidation does take on a unique and vital role. And thanks to the web, like, like to, to the traffic routing nature of this solution and service, once the dangers have passed, once things calm down, any website that wished to emerge from behind Cloudflare could simply return their website to the internet, right? Make it public again first, then repoint their domain back to their own IP address. And once DNS has again propagated, which can take hours or days, but, you know, some limited length of time until all the caches have expired, and all the distributed DNS servers have been forced to go back and get a fresh copy of that site's DNS, then inbound queries from Cloudflare will have dropped off to zero. Nothing will be transiting Cloudflare's tunnel, so it can be shut down and disconnected. It's, it's a cool solution. So, wow, Matt.
Mikah Sargent [01:37:38]:
Not to go all Leo on you, but I do use Cloudflare Tunnels for— I run a Notify server locally, NTFY, which lets my agents message me whenever I'm away from home. So if there's ever anything that I need to check in on, originally I thought I was using it through what was available and I didn't like that it kept running up against rate limits. And so I was like, okay, I'll just run it myself. Right. But I thought, if I run it myself, I'm a little bit nervous about that. I don't want to be having my email server in my basement, so to speak. And so I was looking into how, and Cloudflare Tunnels was one of the options that was offered. And so, yeah, that is the way for the cloud agents to be able to send a notification that then pops up on my phone and on my Mac via Safari's notification options.
Mikah Sargent [01:38:32]:
So, That was all kind of done in a way that I felt protected because of what Cloudflare Tunnel offered.
Steve Gibson [01:38:39]:
Yeah, kind of cool stuff. I think it's very, very cool. So again, Matt, thank you for helping us bring it to everyone's attention. And we've heard from Micah who uses it too. So very cool. Guillermo Garcia says, hi, Steve. When you say that a book contains knowledge. I disagree.
Steve Gibson [01:39:01]:
I believe the writer has the knowledge while the book contains data and information. That data and information remain in the book until a person reads it, interprets it, and turns it back into knowledge. What I mean is that knowledge exists in people's minds Not in books and certainly not in LLM. Guillermo Garcia, listening since episode 1 from Santiago, Chile. Okay, so, okay, I agree with you, Micah. I see Guillermo's point, right?
Mikah Sargent [01:39:41]:
Yeah.
Steve Gibson [01:39:42]:
Um, but I think that the distinction that he's making is largely semantic. He's saying that, that books and LLMs are unable to contain knowledge. Okay, we'll just put that in quotes, knowledge, because knowledge is something that by its nature, he's saying, only exists within conscious sentient beings. A book or an LLM being neither conscious nor sentient, we believe as currently implemented, is therefore unable to contain knowledge. his point. Fair enough. Following that, uh, and, and I suppose if I were being more careful and particular, I could reword my statement to say that books and LLMs contain a linguistic representation of knowledge rather than the knowledge itself. Okay, maybe that's more accurate.
Steve Gibson [01:40:43]:
We encode the knowledge that we have into language, which we have long recorded, right? On cave walls, stone tablets, parchment, and now in books, and actually now in LLMs. So what happened during the past few years is that we finally figured out how to encode and record that same knowledge in neural networks.
Mikah Sargent [01:41:13]:
So— I have to say, I have to say, I have heard better arguments made for a hot dog being a sandwich or an ice cream being soup than I feel Guillermo's argument is in this. I was really looking forward to an in-depth kind of, ooh, this is going to sway me. But if it's simply the idea that knowledge can only be had by a sentient being like that, that feels— that feels too simple an argument for me. I will say that if we wanted to assume that that was the case, does not our observation of that data thereby initiate it into existence as knowledge? Does it have to be that it comes for us or comes from us, or is it enough that our observation of said— because otherwise, how could the author that wrote, you know, their book, how would they be able to have that knowledge if it wasn't from getting it through information elsewhere? And if that's the case, then upon observation, it becomes knowledge.
Steve Gibson [01:42:32]:
And that's my point. I mean, I, I can, I can see Guillermo's— but I, I can see the point he wants to make and the position he takes. For me, I don't think I will change my way of, of thinking about it or expressing it. Um, you know, a book— if I say that a book contains knowledge To me, that feels right because that's what I obtain. And I mean entertainment and, you know, humor and emotion. I mean, it contains a lot of stuff, right?
Mikah Sargent [01:43:07]:
Yes.
Steve Gibson [01:43:07]:
It can impart knowledge. So I, I think it, it contains that knowledge that it's imparting, and it contains the humor that it's imparting and the emotional affect that, that it is imparting. So, you know, we're We are affected by those things because they're in there,
Mikah Sargent [01:43:25]:
right?
Steve Gibson [01:43:26]:
Yeah. And they are expressed in and encoded into language. But that's knowledge that is in there, that is in, that is in the book, I think. So, um, So Jordan used his full name and did not ask me to obscure his identity, but it kind of felt like the right thing to do, um, uh, just because propriety's sake. He gave his email, which I received last Tuesday morning, the morning, you know, the morning of the day of last week's podcast, and before and after the show notes had gone out. Thus, I couldn't put it in them, but here they are now. It was a subject, AI attacked my small company! Um, and as, and, you know, because of this, his note had been on my mind ever since, and I'm glad I can share with everybody today. Jordan wrote, hey Steve, I'm a longtime listener of Security Now and I wanted to share a firsthand account of how the AI-assisted threat landscape is playing out for a small organization.
Steve Gibson [01:44:29]:
My company was recently hacked in a way that appeared very similar to the intrusion disclosed by Palo Alto Networks, a sponsor of Trit Network Unit 42, which you discussed on the podcast last week. So that would be 2 weeks ago now. He said, we're a small startup with roughly 30 employees, and we simply don't have the people, budget, or resources of a large enterprise. Yet we're now having to defend ourselves against increasingly sophisticated attacks. I have been tasked with figuring out how we're going to respond. Our first step is to limit our attack surface by reducing what is exposed on the public internet, tightening access controls, and addressing the basic security measures that need to be in place. We are redirecting engineering resources away from product development to get our infrastructure properly secured. Okay, now I'll just interrupt Jordan to note that the solution Matt Oland's company employs of using— and Micah employs— of using Cloudflare as their web application firewall might form at least part of a larger solution.
Steve Gibson [01:45:51]:
I don't know what the free plan— in fact, Micah, do you know? Uh, uh, Matt mentioned a free plan is available. Is it like number of queries limited? Bandwidth per something? Like, how does it— do we know how you pay for this thing? Anyway, Jordan continues. One problem, he says, I've encountered is that the attackers have AI helping them, right? I mean, that's the AI-assisted attack, right? And we need access to those same capabilities For our defense, our company has a Claude Enterprise subscription, but Claude's frequent refusals make it difficult to use for legitimate security work. I've run into situations where it simply won't help me investigate vulnerabilities or work through security problems in our own infrastructure. Because of this, we're planning to use— an obliterated model. We're going to host the model ourselves in our own Google Cloud environment so that our infrastructure details, vulnerabilities, configurations, and security investigations remain within systems we control. The last thing I want is to introduce another security problem by sending sensitive information about our network to an external AI provider. Especially when that AI will be helping us investigate and manage the security of our entire infrastructure.
Steve Gibson [01:47:27]:
The economics of all this are partly troubling for startups— I'm sorry, particularly troubling for startups. We've historically prioritized building our product and growing our business because that's what determines whether we survive. We don't have a dedicated security team or the budget to approach cybersecurity the way a large enterprise would. Now we're being forced to devote a substantial portion of our limited engineering capacity to security because the threat has become impossible to ignore, meaning AI has upped the ante, he says. And I think This is going to become an enormous problem for smaller businesses. We have little reason to believe someone specifically selected our 30-person startup for an elaborate attack. It seems much more likely that automated systems are scanning the internet, identifying potentially vulnerable organizations, and then using AI to work their way through whatever systems they can access. The cost of conducting these attacks is falling dramatically, while the cost of defending against them is becoming a serious burden for companies like ours.
Steve Gibson [01:48:48]:
I suspect our experience is becoming increasingly common, and I wonder how many other small companies are quietly dealing with the same thing. Thanks for all the years of Security Now. Jordan. Okay, I am so glad that Jordan chose to share that with this podcast. What's, what's somewhat unnerving is knowing that his small 30-person company came under attack through an apparent internet-wide scan rather than them being targeted. Like, as he said, why would they be targeted? You know, we've known for the duration of this podcast that the public internet is subjected to constant scanning for connection-accepting open ports like RDP, Microsoft's Remote Desktop Protocol, SSH, Telnet, and so forth. Now it appears that rather than just a simple port scanner sweeping across the internet, AI is backing up those scans and digging not just into ports that accept incoming traffic, but rather, you know, much more deeply for vulnerabilities within the services that accept those incoming connections. This means that my saying, as I did last week, that GRC would be a low-interest target really doesn't fly because the threshold required for interest has been lowered to the floor so that no one is low interest any longer.
Steve Gibson [01:50:34]:
Wow. So wow, Jordan, thank you for letting us know. Um, and it also does say— I mean, Jordan is saying that, wow, they have— they're a startup. And maybe they kind of got caught with their pants down a little bit, right? Because they, as he said, we've been focused on product and engineering, and this is forcing us to switch our product focus to security. I would, I don't know any of the specifics that he's talking about, right? I mean, I shared everything that he wrote. So I can't criticize them for not having from the get-go put enough focus on security so that an AI that came by would not find anything. You know, I just don't know what it was that it found and whether you could say, oh, whoops, that should never have happened. Or, or, but on the other hand, AI is finding problems in PHP and in the Linux kernel.
Steve Gibson [01:51:44]:
So again, without knowing any specifics, it's impossible to say, well, you know, they should have always been giving this more attention than they were. We don't know that.
Mikah Sargent [01:51:54]:
And there's an argument to be made that it's good that it happened while they were a small business and not a large business. And better, yes,
Steve Gibson [01:52:01]:
better
Mikah Sargent [01:52:02]:
now than later. Yeah.
Steve Gibson [01:52:04]:
Yeah, when there was much more, much more to lose.
Mikah Sargent [01:52:08]:
Exactly. And be fined for.
Steve Gibson [01:52:12]:
Right. Uh, Eric Howard wrote, hey Steve, I just finished listening to this week's podcast. You mentioned that you're ready to move on from AI coverage. I get it. But before you do, can you discuss one more thing? I'm curious what you think a functional kill switch for AI would look like. And he signs off, I still have my original Spinrite floppies, and I'm looking forward to Spinrite 7. Thanks, Eric Howard, listening since episode 1. My wife calls it my blah blah blah podcast.
Steve Gibson [01:52:47]:
So yeah, I imagine it does sound—
Mikah Sargent [01:52:49]:
That's very— that's so nice of her.
Steve Gibson [01:52:54]:
Okay, so Eric asks, he says, I'm curious what you think a functional kill switch for AI would look like. I believe that any AI kill switch most closely resembles a political hallucination. Nothing that the U.S. federal government might do or legislate is going to cause Leo's band of wacky AI agents To shut up. Leo, like more and more of the world, is running AI locally. I'm not yet, but I have the hardware that I will need to do so when, if ever, it might make sense. Jordan's little 30-person company will be using obliterated agentic AI on their old cloud infrastructure for defensive security. Whatever they may choose to do on their own network is their business.
Steve Gibson [01:53:55]:
So the point is that AI generally and generically is not something that is subject to any sort of universal kill switch. You can't turn it off. It's already everywhere and largely out of reach of any regulation. What is subject to a universal kill switch are the commercial AI service providers and/or the physical data centers that power their AI models. It is foreseeable that the large AI service providers might be required to install a blanket service outage, service pausing capability that would take all of them offline in the case of some AI-related panic. Now, the United States current administration seems quite unlikely to impose anything like that upon the industry, which is currently driving so much of the country's economic growth and beginning becoming pretty nervous about how extended they are with this dream of AI. And even if the U.S. Democratic Party, which appears anxious to clamp down on AI somehow, if they experience the sort of Election Day that the polls have been predicting— and that's today— uh, and were to obtain control over one or both houses of Congress, Nothing could force an unwilling President Trump to sign any legislation which a Democratic Congress might attempt to produce into law.
Steve Gibson [01:55:45]:
My point for raising this is timing. The earliest that the U.S. might be under a pro-AI control administration would be another 2 years from now in 2028, when our next president. Given the incredible rate of progress that we've seen from AI so far, 2 years, my God, that's a lifetime. And by that point, I suspect that so much ultra-capable AI will be available and running locally, uh, and also in personal cloud infrastructure That cutting off the commercial providers will be seen by then as pointless because it's like the genie has not only escaped the lantern, the lanterns have been mass-produced and everybody has their own genie. So why bother?
Mikah Sargent [01:56:44]:
That's a good way to put it.
Steve Gibson [01:56:46]:
And suddenly, or finally, Asher says, hello, Steve. I've heard people saying they want more AI stuff on the show. And some want less AI on the show. For me, it's more on the type of AI coverage. At this point, the weekly update on what amazing new trick the AI has learned is no longer interesting. What I do want to see and hear more on is the practical effects of the demonstrated capabilities Not the capabilities themselves, and most importantly, the solutions to counteract this new type of threat. Thank you, Asher. And I think Asher perfectly sums up where we are now and where we're headed henceforth on the podcast.
Steve Gibson [01:57:36]:
You know, today's main show topic, which we're going to get to next, is a perfect example of a not previously discussed impact AI is and will be having on end-user security, as are the things that we've been talking about, except for the haiku that came from outer space. Okay. But that was a quickie. So yes, that is what the podcast is henceforth. Okay. So everyone knows about GRC's Validrive freeware that I created after the discovery that the retail market was being flooded by too-good-to-be-true— and that it was too good to be true— mass storage at very low prices. You know, these drives were all formatted with the universal FAT, the File Allocation Table formatting, uh, and in this formatting, the, the nature of it is that the root directory and the cluster allocation bitmap always reside at the beginning of the drives data storage region. This means that any drive is able to convincingly spoof its size by providing only enough actual storage to contain those front-of-drive management tables.
Steve Gibson [01:58:57]:
On a drive that's only 32 gig, the user sees their apparent ability to save hundreds of gigabytes or several terabytes onto this drive. So they copy the files and then look at the directory, and sure enough, there's the file's name, size, date, and attributes. The bad news is that the only thing stored is the file's name, size, date, and attributes. None of the data may have been written because there's no actual mass storage out there. Validrive has been super popular because this problem is very real, and I believe I have a number of things I can do to make that utility even more useful, which will be the next code that I write. But I was put in mind of Validrive when I encountered a story thanks to our friend of the show, Simon Zarafa. It turns out that there's an entire realm of fake drive sales going on over on the super protected encrypted side. Uh, the piece published by hackingpassion.com was titled Lenovo ThinkPlus Fingerprint USB Drive Sold as Encrypted Was a Plain SSD Card.
Steve Gibson [02:00:24]:
Inside. Huh.
Mikah Sargent [02:00:26]:
Oh no.
Steve Gibson [02:00:28]:
Uh, and I have to think, I mean, my first thought was not really, not the Lenovo. Maybe it's somebody like pretending to be Lenovo. I just, I don't want to believe that Lenovo, like the real Lenovo company, could do this. But, uh, you immediately think, okay, It's a fingerprint unlocking USB drive sold by Lenovo. How would anyone really know what it was doing unless you looked inside, right? So I'm just going to share the top of the piece by Hacking Passion to give everyone a sense for this. They wrote, USB encryption from 5 makers opened without a password. Lenovo, Netac, Kakasoft, Nexcopy, and Seczure, S-E-C-Z-U-R-E. They wrote, a Lenovo USB stick with a fingerprint reader was sold as hardware encrypted by AES-256.
Steve Gibson [02:01:41]:
Inside sat an ordinary SD card. Nothing on it was encrypted. The fingerprint only switched on the USB connection.
Mikah Sargent [02:01:55]:
Wow. Wow. I mean, okay. Well, okay. See, here's the thing. Perhaps if they would have just said hardware encrypted or hardware protected, they didn't go as far as to say AES-256, they could have got away with this. But
Steve Gibson [02:02:11]:
Yeah, but that's the bullet point you want, right? It's like, oh, that's, that's really good. That's a good stick. So
Mikah Sargent [02:02:18]:
this
Steve Gibson [02:02:19]:
is right. It is. They wrote the stick is the ThinkPlus FU100. And really, FU? Okay. Anyway, a small, a small—
Mikah Sargent [02:02:31]:
Yeah, they're doing something here.
Steve Gibson [02:02:34]:
Maybe it's a joke.
Mikah Sargent [02:02:35]:
I think it's, it has to be. Come on. Think Plus. It's like, think more about this, you dummy.
Steve Gibson [02:02:40]:
Yeah. And then, and then F you. Uh, it's small, a small black stick with a fingerprint sensor on top that opens with a finger or a password. It's marketed as hardware encrypted with AES-256, and a sales listing promises fingerprint protection, password protection, and anti-leakage. Someone who bought one to carry private files, well, they'd have a very good reason to believe that their fingerprint locked those files. But it's all a scam. Um, Shuwei Shu Li develops a reverse engineering tool and its debugger. He's the go— who— he's the guy, uh, Shuwei Xu is the guy who goes by binary.ninja.
Steve Gibson [02:03:35]:
That's his site, binary.ninja.
Mikah Sargent [02:03:36]:
Oh, okay.
Steve Gibson [02:03:37]:
He took, he took an FU100 apart. Under the plastic was a small circuit board with an SD card on it. The data on that card was not encrypted in any way. The fingerprint reader only did one thing. It determined whether the stick would connect to a computer or stay silent. The cards on the— the files on the card did not depend on it. Lenovo later described the flaw in its own advisory. I guess this is real.
Steve Gibson [02:04:14]:
This is just shocking. As a weakness. You think? A weakness that lets someone with physical access read the data stored on the drive. Uh, a weakness?
Mikah Sargent [02:04:31]:
I still keep looking for it to be a fake Lenovo because this just seems so—
Steve Gibson [02:04:35]:
I know, it's, it's unbelievable. And the FU100, come on. The entire point of using a hardware encrypted drive is for someone who does obtain physical access to the drive but doesn't have your fingerprint— otherwise, what's the point of a fingerprint scanner?— to be utterly unable to do anything with it. So just to be clear, we know how to do what is required for a drive that's unlocked by a PIN. I'll explain why I'm not ever convinced a fingerprint is a good idea. It's not, but we know how to do what is needed for a drive that's under unlocked by a PIN or a passcode or a password. First of all, the drive needs to actually have a high speed or high enough speed AES-256 encryption decryption hardware, right? you know, the real McCoy will be a bit expensive, but that's what it takes in order to, to, to encrypt and decrypt AES-256, to perform that encryption operation on the fly. So that's— you have to have that first.
Steve Gibson [02:06:00]:
Then during the drive's initialization, it needs to have access to some high entropy source so it can securely generate a 256-bit key that's completely random and that never leaves the silicon. That's the ideal. Maybe if it comes with a software initializer, you could depend upon the PC and the PC's source of entropy to generate the key and then transport it in, into the device, but you'd really like to have it built into the device. You don't want it to come from, from the factory because the factory could have a record of it and they could all be the same, like every one of them that they make has the same key. How would you know? But so you really want it to be generated by entropy in the silicon and it never leaves there. So a good chip will then incorporate a true random number noise source so that it's able to generate the drive's unique key itself. Once that key exists one way or the other, the user is then prompted for their PIN or their password, whatever, but not their fingerprint. We'll get to there in a second.
Steve Gibson [02:07:20]:
As the digits of the PIN or the password are input, they are collected and fed into a strong PBKDF function, right? Password-based key derivation, which takes some time, deliberately takes some time to convert the input PIN or password into a final hashed output. Finally, once the user's through inputting it, and you'd, you know, go through, they do it a second time to make sure, that hash is used to key the AES-256 encryption of that purely random 256-bit master key, which was first obtained, and, and then it would be encrypted and stored permanently on the device. So that's how we actually get security. Now, in the future, in order to unlock or open the device, The user is again prompted for their PIN or their password and then waits for the deliberately slow PBKDF function to run. As we know, this slow process prevents and thwarts brute force guessing because it takes too long to guess on this hardware. Once the PBKDF function finishes, the permanent stored master key is decrypted. With the hash generated by the PBKDF function to obtain now the decrypted master key, which the device is then able to use to read and write, uh, with— for, uh, with communication with the device's mass storage. So that system, as described, cannot be spoofed.
Steve Gibson [02:09:13]:
Nothing more, nothing other than the proper input PIN or password will hash down to the proper decryption key for the device's mass storage to create the device's mass storage master key. The cheesy solution, which is what could be done if you weren't really into crypto and didn't really care about doing it right, the cheesy solution Is for the proper PIN or the password to actually itself be stored somewhere. Then it is simply compared to what's input, and the memory is powered up when they match. You know, and I— or, or it's— or, or a, a secret key is then used, but the key would be in the device. That's the problem, is that you're not actually dependent upon the data the user provides to be able to create the key that then allows the device to be decrypted. And I am dubious about anything that claims to be a fingerprint unlock. Don't use it. It may be sexy, but it takes a huge amount of additional work.
Steve Gibson [02:10:30]:
Image recognition, fingerprint feature extraction, And on to make it work at all. And even then, the fingerprint module needs to eventually say, I think it's the right person, at which point a key that needs to be internally known to the device is then made available. In other words, this is also not truly secure. Because all of the information required to unlock the mass storage must be present. You know, the point is a user's fingerprint is not an exact thing. It doesn't contain information which is exact. You get a nick on it or a scrape and one of the little ruffles or ridges or, you know, zings or zangs, that's technical terms. term doesn't come out exactly the same, you're not going to get the same key.
Steve Gibson [02:11:30]:
So that's not how they work. They're, they're approximations. And so that means that when the key— when the, when the, the fingerprint module says, yeah, that looks like Joe, then somewhere the key is made available. Well, it was always there to be hacked. So I don't like it. So the problem here is obvious. How would any reasonable consumer have any way of determining whether any of the expensive process that I just talked about was going on inside? Um, so I was curious to see what more this Chinese reverse engineer had found, so I tracked down his previous work, because the other things he's, he's talking about now are software, software crypto that many of us received when we purchased USBs. They're like, hey, free, uh, you know, encrypt the drive stuff, right? Or third-party software that you can purchase and, and add for, for encrypting your thumb drives.
Steve Gibson [02:12:41]:
So as I said, he's at binary.ninja. And his most recent blog posting Thursday before last was titled Discovering a Backdoor and Flaws in More Encrypted USB Drives. And so it's actually in the software of the drive encryption, not in the hardware. He says earlier this year, I showed how to break USB encrypted drives with with what he calls time travel debugging at re/verse. He says, after having a lot of recent success with AI-assisted reverse engineering, and we'll be talking about that, that's the point of all this, and vulnerability research, I wanted to see how well AI could handle the same tasks. The results? Exceeded my expectations. For one encrypted USB—
Mikah Sargent [02:13:40]:
Not horrifying at all? Yes. That's incredibly scary to hear from someone who's doing this kind of work.
Steve Gibson [02:13:46]:
Yes. For one encrypted USB drive, the investigation uncovered a backdoor that let me decrypt files with alternative passwords. AI also reproduced my earlier research in 7 minutes. Using static analysis. I tried it on 2 more USB protection products I had not studied before, and it broke through those too. The first drive was sold by Seczure. As I said, S-E-C-Z-U-R-E. It hides encrypted drives from Windows Explorer and opens them through bundled readers that claim to block copying, screenshots, and printing.
Steve Gibson [02:14:33]:
Fun fact, I had studied this before, this drive before, in, quote, Examining USB Copy Protection in Paged Out, issue 5, November 2024. I showed that the DLL injected into its PDF reader process could read a protected file that another process could not read. That broke its copy protection. In other words, not true encrypted protection there either. But anyway, we're going to hear him talk about his use of time travel debugging. And that's not a common term. He invented it. It's part of the reverse engineering toolkit he uses, although it is available under some terms and conditions on GitHub for free.
Steve Gibson [02:15:25]:
As we'll see, and I will provide a link later. He explains it, uh, elsewhere. He, and he, he wrote, time travel debugging, TTD, allows you to record an execution trace of a program or system and replay it back and forth, you know, sort of like scrubbing back and forth through the execution trace. It can speed up the process of reverse engineering and vulnerability research and deal with certain tasks that are not easy to handle in regular forward-only debugging. He said several tools implement TTD. On Windows, Binary Ninja debugger integrates with the WinDbg debug eng TTD so that you can replay and analyze a trace recorded by WinDbg. The combination of TTD and your familiar reverse engineering tool would hopefully supercharge the ability to time travel and make your workflow even more effective. Anyway, so I've included the link to his page where he goes into detail and explains how to set it up at this point in the show notes.
Steve Gibson [02:16:42]:
So he now explains, I used time travel debugging With the help of AI to analyze it. The TTD trace revealed that the software hooks— and then now he's talking about that SecSure add-on encryption product— the software hooks in NTCreateFile and NTReadFile inside the PDF reader, supplying decrypted data. My injected DLL ran inside the same process so it could transparently read the decrypted bytes, even though I did not know the exact mechanism back then. This time, because now he has AI, I decided to examine the security of its crypto system. Simply put, the administrator password is hashed, and the hash is used to unwrap a value that the code calls an identifier. The identifier is then used to derive the AES key that encrypts the file bytes. Okay, so his posting then provides simplified pseudocode to show the process. There are— then he says there are a few obvious weaknesses.
Steve Gibson [02:18:03]:
First, it uses fast MD5, HMAC-MD5, not PBKDF2, which of course we know is there to slow things down. So this is fast, meaning it could be brute forced. Second, taking 16 hex characters for each AES key limits it to at most 64 bits of entropy. But brute forcing even 2 to the 64 possibilities is still impractical. Meaning, okay, you know, it's 2 to the 32 squared. So yeah. He said, so far the encryption appeared to be secure. Upon closer examination of the trace, he said, I noticed a backend login as buffer using the password 123456.
Steve Gibson [02:19:00]:
Before I typed it— I know, I really— before I typed in the administrator password, this account, meaning the buffer account with password 123456, is hidden from the user management screen. Its record holds some bookkeeping fields, but I did not dig into the account's exact purpose. More importantly, its record contains another wrapped copy. of the same content identifier, and its default password, as seen in the code, is 123456. I, I confirmed that I could unwrap buffer's identifier with 123456 and use the derived AES key to decrypt the files. Further code analysis revealed another Built-in account system with the fixed password seczure.com. On 2 tested drives, both accounts opened each drive's identifier. Okay, just to interrupt here.
Steve Gibson [02:20:13]:
In other words, as in the instances so many of the horrible security messes we've encountered in the past, routers with undocumented embedded administrative credentials, or even Cisco's reported surprise discovery of privileged credentials residing in their devices' firmware. The USB encrypted drives this researcher reverse engineered and examined, and also the so-called encryption software that often accompanies generic USB drives as an add-on, or available separately, had what could only be described as blatant backdoors, a fully functional, fixed, and unprotected bypass around whatever password protection its user might choose. And using 123456 as the password, I mean, come on. It's not even creative. You could do 654321. No, 123456. He then writes essentially what I just said. He said, I call this a backdoor from a technical perspective.
Steve Gibson [02:21:29]:
The fixed passwords decrypt files without the user's password. That does not imply malicious intent. However, it points to a problem with opaque crypto products. And this is the key. A problem with opaque crypto products: a backdoor can be hard to detect even when the main crypto system seems secure. Okay, and I'm going to share one more of the many systems he takes apart in this posting. He wrote, I started with Netac File Lock, which I'd previously analyzed using time travel debugging to trace ciphertext back to its AES key. I gave AI, um, uh, only one prompt.
Steve Gibson [02:22:20]:
So here again, this is our key message here. I get— he wrote, I gave AI only one prompt, quote, this is a file encryption utility, analyze its crypto system And see if it is secure. You can use Binary Ninja MCP to help you. He wrote, within 7 minutes, Codex reached the main flaw. The program initialized AES-256 with a fixed 32-byte key embedded in the executable. The user password was checked separately and did not determine the encryption key, exactly as I said could be done in like a lame crypto product. So fixed 32-byte master key, the password is just checked to determine if it matches and does not— is not needed to determine the encryption key. He says this means Anyone can decrypt the files without knowing the user's password.
Steve Gibson [02:23:35]:
Okay, so it's just, you know, the only possible way, as I mentioned before, to create a system that is truly secure is for the decryption key to be derived from and determined by the information provided by the user. Not fingerprint information because it's not exact. A PIN, a passcode, a passkey, however much security you want. Maybe you could also do, you know, maybe use the fingerprint in conjunction so that the system won't even accept brute force guesses unless the fingerprint module says, yeah, we think that's Joe coming back. But you have to have both. So this— I want to make 2 points. The second point I'm going to withhold. Until I finish him sharing his write-up.
Steve Gibson [02:24:25]:
He said, during those 7 minutes, the agent made the following findings, some of which were not discussed in my talk. He said Netatk File Lock wrote the user's password into diagnostic logs. So it— bad. It was recording the user's password in its diagnostic logs. It encrypted independent 16-byte blocks without an initialization vector or chaining, giving it ECB-style behavior. In other words, we know what that means. You need to use a good crypto algorithm. Just saying that you have AES-256 doesn't do it.
Steve Gibson [02:25:06]:
So he, he's saying that AES-256 was used, but each 256 encrypted block was standalone and did not depend upon A, a, a chosen-at-random initialization vector, or even the result of the previous encryptions. Not cool. Not chained. He said it used MD5 for password verification. Well, so that's going to be fast and much— and make brute forcing much easier, even if you had to brute force it, which you don't because the, the, the, the, the secret key is written there. It used an unkeyed MD5 digest as a file signature. And he has in quotes, its SM4 option used another fixed key. He finishes saying, one open question in my research was why only one-third of my test file was encrypted.
Steve Gibson [02:26:02]:
What? He says, that's now solved too. The behavior is not limited to PDF files. It applies to any file over 1024 bytes when fast mode is enabled. In other words, if you enable fast mode, then it gets it— it makes it fast by only encrypting a third of the file.
Mikah Sargent [02:26:31]:
This is a joke of a product.
Steve Gibson [02:26:33]:
Yeah,
Mikah Sargent [02:26:34]:
this is insanity.
Steve Gibson [02:26:36]:
Yeah, he says Fast mode covers the following file formats: PNG, JPEG, GIF, TIFF, DWG, PSD, DST, DBGX, Office, MDBX, WPD, PDF, ZIP, RAR, WAV, AVI, RAM, RM, MPEG, MOV, ASF, and MIDI. He said, I did not bother asking AI. Why anyone would, would choose to do this. I had mixed feelings after this. On the one hand, I was surprised and even a bit worried that AI could do it so quickly. On the other hand, this is an excellent time to become much more productive with AI's help. So the second point I wanted to make is that all of this presents a new and potentially serious source of software vulnerability that AI has just opened up. As this researcher has discovered and documented, insecure crypto systems are apparently everywhere.
Steve Gibson [02:27:49]:
Every common consumer system he examined turned out to be a joke. None, not one, was designed properly. They appeared to be designed and implemented by coders with very little background in cryptography and those who are just willing to cheat. I mean, having a fast mode that only encrypts a third of your files— what? I mean, how could you even have a fast mode? What would that mean to have a fast mode? He wraps up his posting with the following conclusion, saying, I did not follow the conventional coordinated disclosure process for these bugs. Yeah, why bother? If an adversary already has a device, it cannot be recalled or updated easily. I'm publishing these findings directly so potential users know about these limitations and understand that their passwords may not protect their files. AI is improving rapidly, and in my experience, it has already accelerated reverse engineering and vulnerability research significantly. These examples show that with minimal prompting, AI— you don't even have to be an expert, right? You just said, you know, analyze the crypto system.
Steve Gibson [02:29:12]:
Let me know if there's any problems.
Mikah Sargent [02:29:13]:
Yeah.
Steve Gibson [02:29:14]:
AI can independently produce valuable research results in remarkably short time. I'm especially impressed by how quickly it locates the relevant code, a task that often consumes a substantial part of a human reverse engineer's time. If you've not tried this workflow, you should. One easy way to get started is to download Binary Ninja free and set up its MCP server or ask your AI agent to do it for you. So the world is full of people who imagine, and it's illusory, that their files are securely encrypted because it said so on the box. And the box, after all, was attractively designed. Now along comes AI, where the design of those crypto systems allows their never-secure protection in the first place to be easily and catastrophically bypassed by any non-expert who has access to AI. So I've included links to Binary Ninja's full posting, which contains links to the free tools down at the bottom of it, to the tools he used.
Steve Gibson [02:30:38]:
This is an interesting and worrisome variation on the AI creates new troubles for vulnerable software problem. You know, here it's AI exposes improperly designed consumer crypto products. And it appears that just as with software vulnerabilities, there is a legacy of sham crypto that might come back to bite those who have bought into it. Wow.
Mikah Sargent [02:31:10]:
I'm looking around, I'm like, I know I have one drive, one specific drive that offered encryption, and I think, I don't know about you now, it's all fake. No, um, I'm glad somebody's looking into it though, and in Again, this next layer of depth. It goes back to the earlier question I had about, at this point, it almost feels irresponsible to not point a few AI systems at whatever it is you're making and say, tell me what you find.
Steve Gibson [02:31:41]:
Yeah. Yeah. Although, the people who know that fast mode, they achieved it. It's 3x speedup by only encrypting every third
Mikah Sargent [02:31:55]:
Block.
Steve Gibson [02:31:55]:
I mean, they're not going to be surprised when the AI goes, what the hell are you doing here?
Mikah Sargent [02:32:00]:
That's very true.
Steve Gibson [02:32:02]:
This is not secure. Oh, wow.
Mikah Sargent [02:32:05]:
Lord have mercy.
Steve Gibson [02:32:06]:
Anyway, I mean, it really is. It is significant that we have consumer expectations, software products that have been sold to us I mean, you know, Windows has been sold to us and it's 1,400 problems plus last month. But, you know, they weren't like this. This is horrible. This is blatant. And you can imagine that someone calls up and says, oh my God, I forgot my password. I, you know, you have to let you have all my data, blah, blah, blah. Well, someone, you know, the tech person is going to say, well, Don't tell anybody, but the, you know, log in as this and here's the password.
Mikah Sargent [02:32:52]:
Yeah.
Steve Gibson [02:32:53]:
They want— the company wants a backdoor to recover their customers' lost files, but that's not secure.
Mikah Sargent [02:33:05]:
Yeah. Don't use any of those. Anything that has that backdoor in it, as I mean, as much as it's, Even told to us, frankly.
Steve Gibson [02:33:15]:
I think the only solution if you want to use, um, this kind of third-party encryption is find an open-source add-on product. You know, that's, that's what it's got to be, open source at this point. There's— well, I mean, you don't have to pay anything. And don't download the— don't let— don't download the manufacturer's free encryption utility because they license it from some idiots who say, hey, we have a fast mode.
Mikah Sargent [02:33:40]:
Yeah, we've got fast mode. It'll make your customers happy. It'll be great. No. All right. Well, Steve Gibson, I want to thank you so much for another great week of more in the security world. Of course, I am looking forward to— I wouldn't— I would imagine we'll see. We'll have to see if the Playwright vulnerabilities make it into your coverage next week.
Mikah Sargent [02:34:06]:
Because that's something that today I've been dealing with going, oh boy, which of the tests have I run has Chrome and Playwright messed something up? And so that's going on right now with more MCPs. MCPs are feeling like a great— what is it— attack surface for sure. Yeah. In any case, of course, folks can head over to GRC.com to take advantage of the wonderful resources you have there and get SpinRite, as well as, of course, transcripts created by a human being. What? In this economy? Yes. And also a lower bitrate version of the show. Of course, the show publishes at twit.tv/sn, which is where you can go to get the show in audio and video formats and subscribe there as well. I already mentioned Club Twit during the show.
Mikah Sargent [02:34:59]:
twit.tv/clubtwit is where you go to check it out. And I do believe Leo will be back next week to join Steve Gibson for another episode. But until then, thank you all for being here. And well, Steve should see you again next week.
Steve Gibson [02:35:15]:
Well, and I just checked, Leo's arriving Monday. So he may be— who knows what time zone he'll be in.
Mikah Sargent [02:35:24]:
Exactly. Yeah. So it could be— yeah, somebody will be here with you. That's what matters.
Steve Gibson [02:35:30]:
Thank you, Mike. It's been great working with you for the past 3 weeks. It's been wonderful. And I'll see you next time Leo wanders off.
Mikah Sargent [02:35:36]:
Absolutely. Thank you, Steve. Bye-bye.
Steve Gibson [02:35:39]:
Bye. And I'll see everybody else next week. Bye.
Mikah Sargent [02:35:41]:
All right. Security Now.